Volantis has raised $88M to attack the bottleneck that decides how fast an AI model can answer: the speed data moves between a chip’s processing cores and its memory.
The Series A was led by angel investor Lachy Groom and Abstract Ventures, with Kleiner Perkins chair John Doerr and former Intel AI products chief Naveen Rao among more than a dozen participants.
The founding team brings serious chip pedigree, including engineers from Nvidia and Broadcom and the first commercial implementation of CoWoS, an interconnect widely used in AI accelerators.
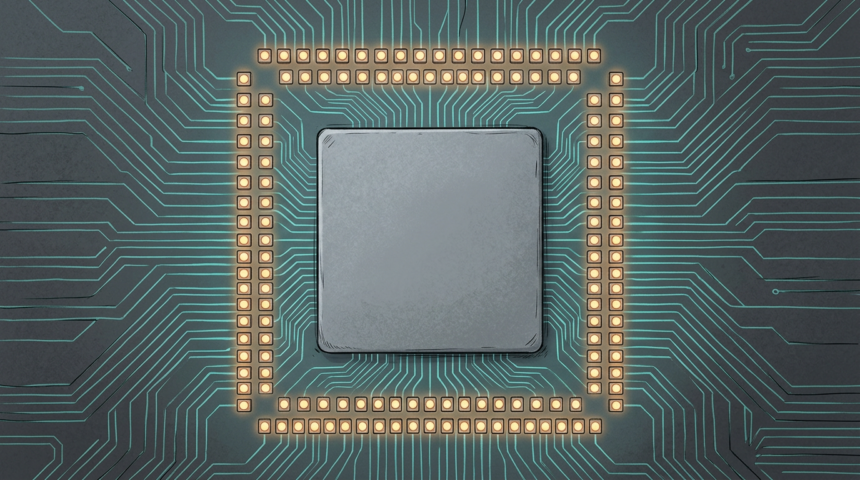
Volantis is building an inference-optimised chip around a custom optical memory interconnect. Today’s GPU wiring reaches about five millimetres, capping how many memory modules fit on a package. Volantis says its links span more than 200 millimetres, enough for 220-plus memory chiplets and more than 30 times the memory bandwidth of current accelerators.
The light comes from VCSELs, microscopic devices that are cheaper and easier to manufacture than the lasers optical gear usually relies on. Volantis will ship the silicon inside the A-1, an inference appliance about a third the size of a server rack with 10 terabytes of memory and 250 terabits per second of bandwidth.
Chief executive Tapa Ghosh frames the prize as real-time frontier inference: a coding agent that finishes a task in 30 seconds rather than 30 minutes.